
A stalled electric vehicle charger can derail an entire journey. For one German startup, that ordinary failure point became the foundation for an AI-driven rescue system now fielding driver calls every 90 seconds across more than 90 languages.
Lemonflow builds conversational agents specifically for EV charging networks. One tier assists stranded drivers over phone, chat, email, or WhatsApp. Another monitors charger infrastructure in the background.
The company entered a market where between 15 and 25 percent of charging attempts in Europe end unsuccessfully. Meanwhile, battery-electric registrations climbed 30 percent in 2025, and thousands of charge point operators now manage public stations. Drivers hitting a dead charger often faced long call center queues or no immediate help at all.
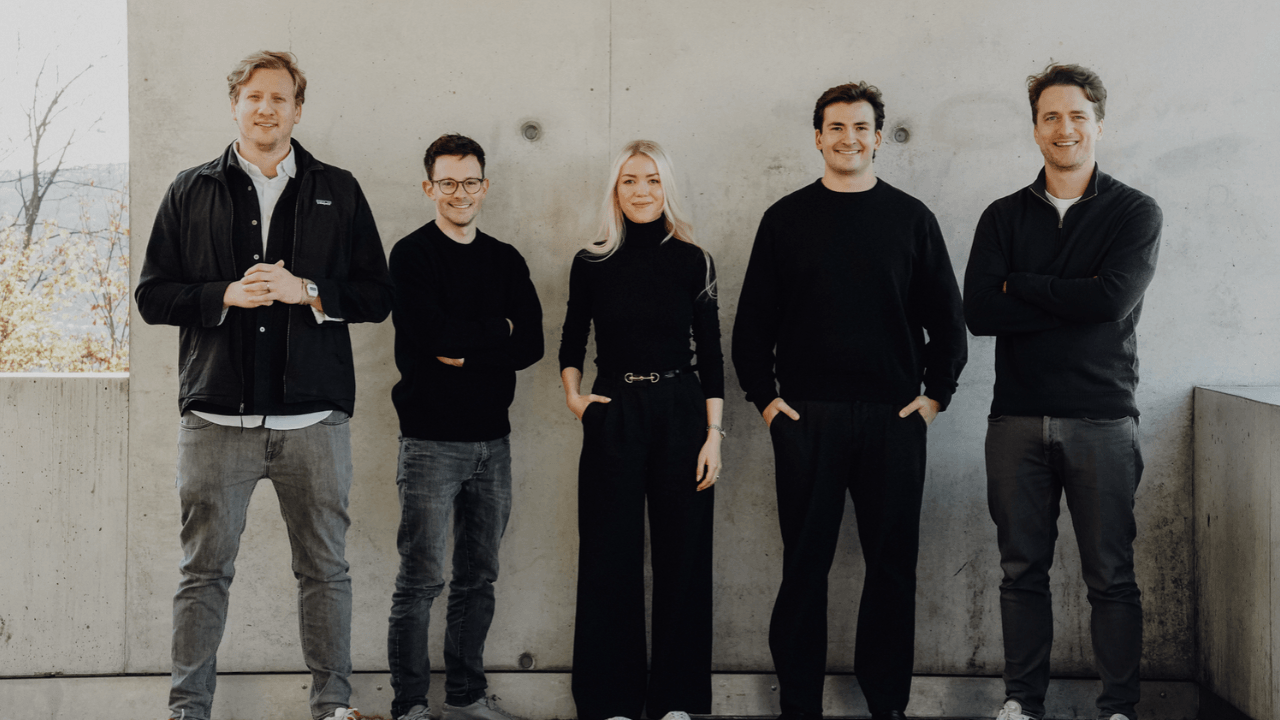
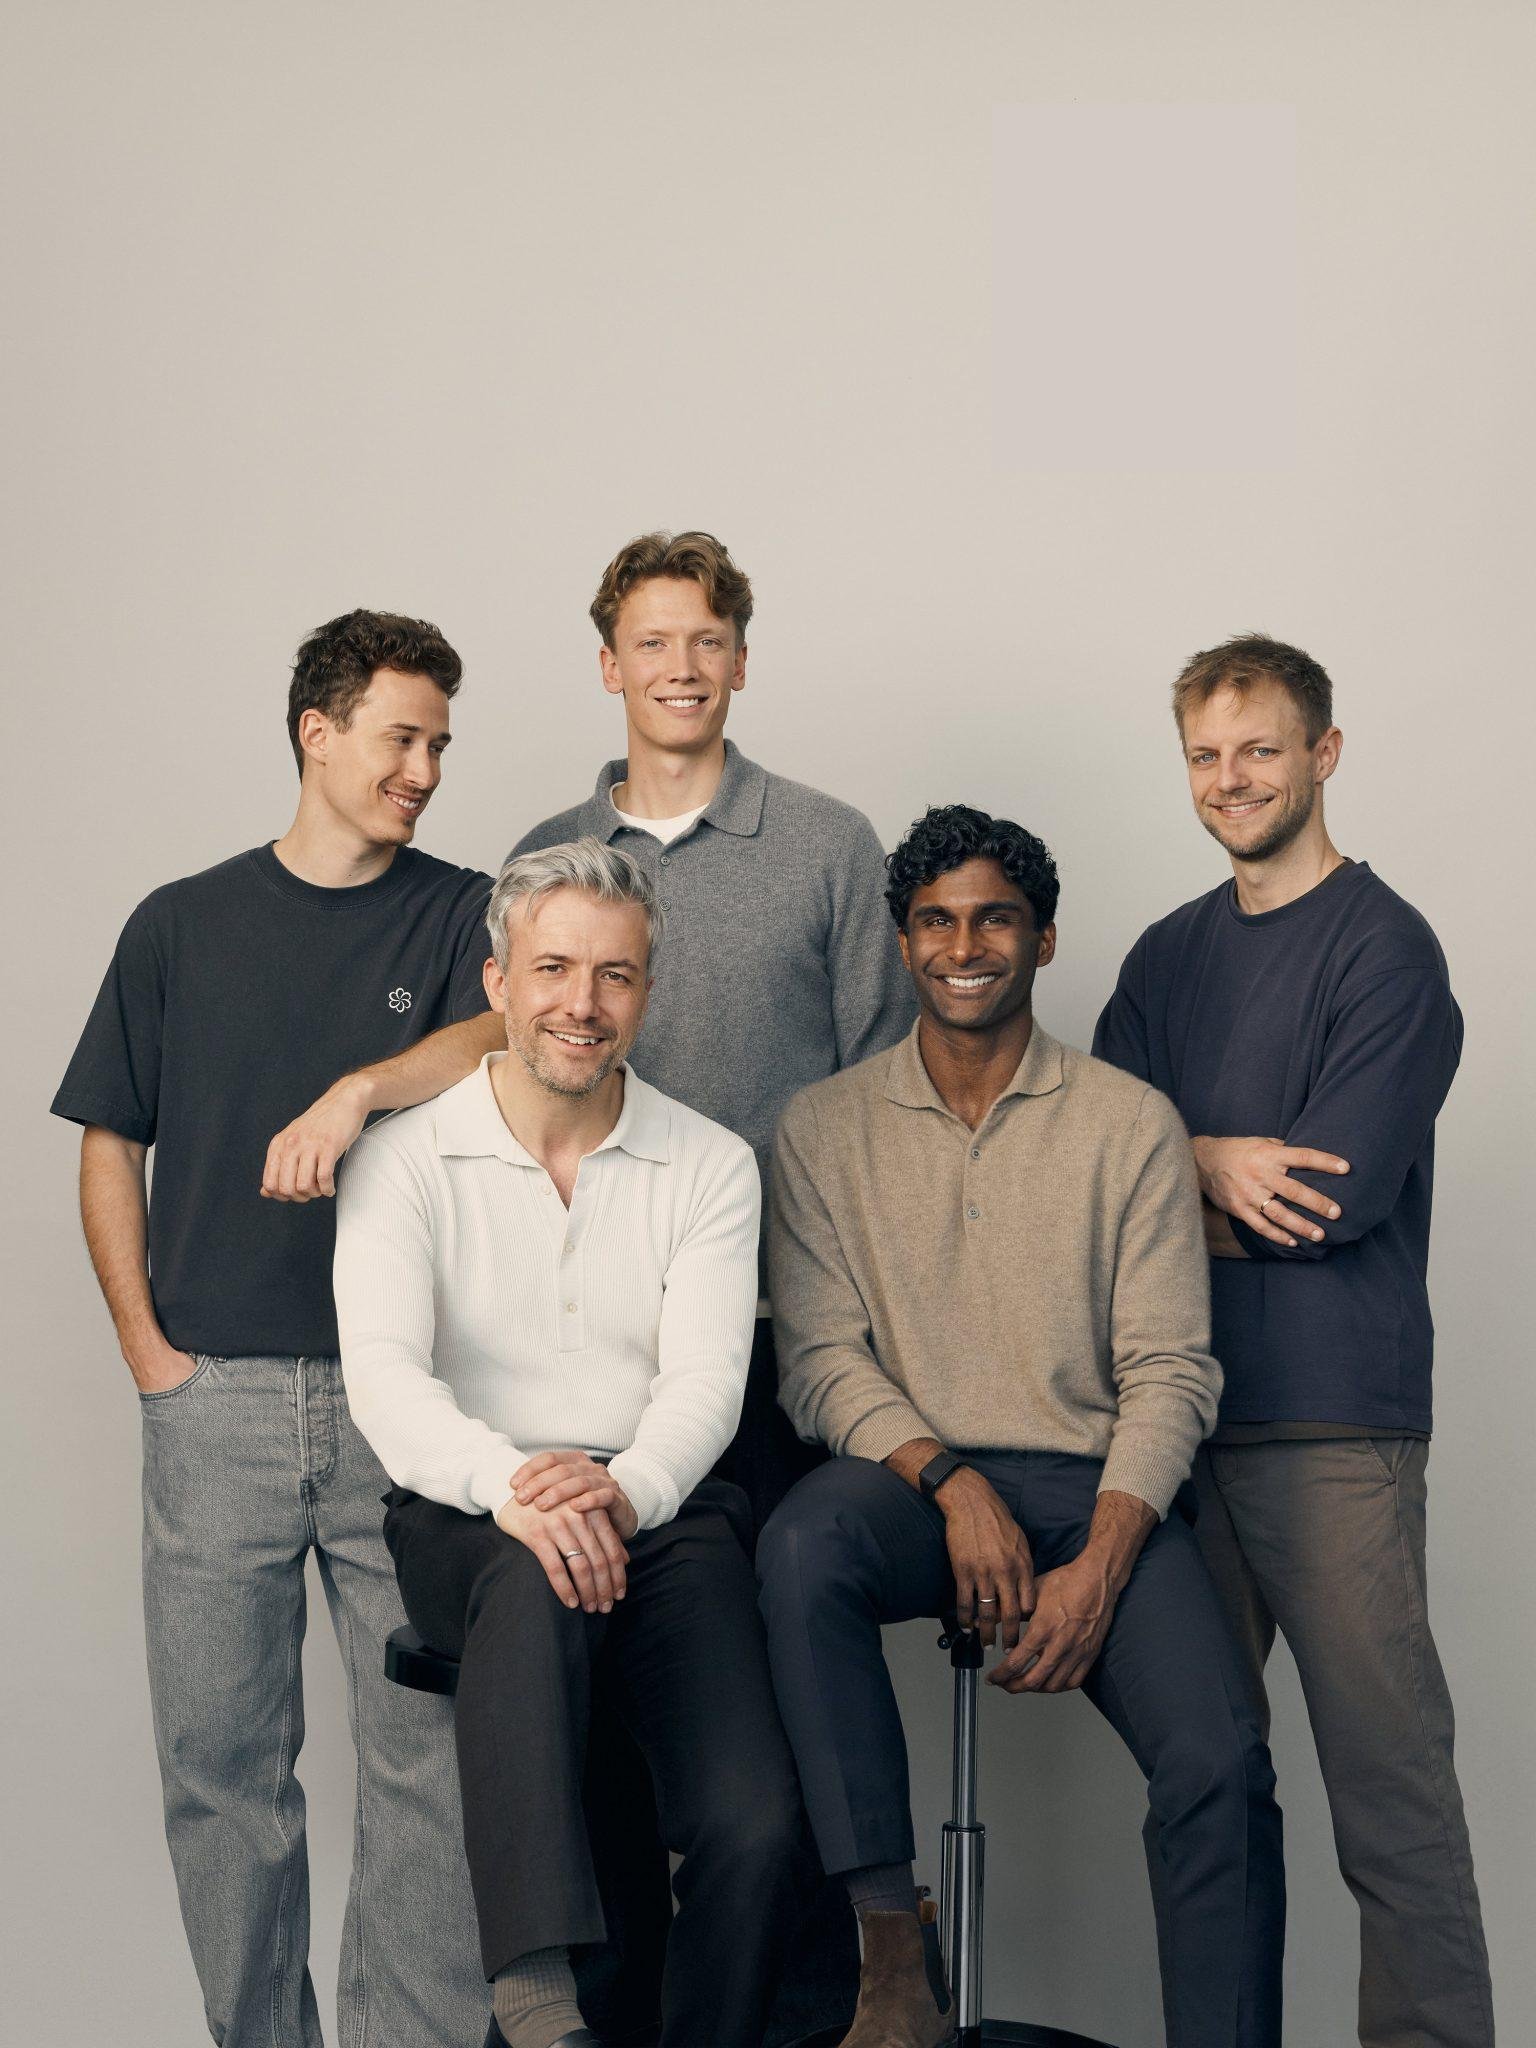
The founders previously worked with major mobility players and watched these failures up close. Their response was an automated platform that diagnoses live hardware problems through natural conversation. Reaching that goal, however, demanded clearing several technical hurdles.
Latency topped the list. Testing showed that response times beyond 800 milliseconds trigger barge-ins, where frustrated callers interrupt the agent and break the conversation flow. Managed API endpoints proved unreliable under load, with peak-hour latency spiking from roughly one second to over 1.7 seconds and occasional HTTP 429 rate-limit errors. As a result, lemonflow moved to self-hosting the open Gemma 4 model on Google Cloud TPU v6e hardware located in the EU.
The switch delivered direct control over the serving stack. Engineers built deterministic guardrails for EV-specific logic, prompt injection defense, and protocol standardization across roughly 30 distinct Charge Point Management Systems before requests ever reach the model.
Custom vLLM optimizations paired with memory tiering between TPU and host memory allow a single slice to keep hundreds of operator-specific agents ready without recomputing context. An intelligent gateway routes live voice calls ahead of web chats and postpones automated test workloads to off-peak windows.
Gemma handles more than 99.9 percent of live turns. Fallback paths to self-hosted GPUs and Gemini Enterprise endpoints act mainly as deployment buffers. The architecture also anchors Lemonflow’s Agent Coach, a background system that continuously refines agent behavior.