
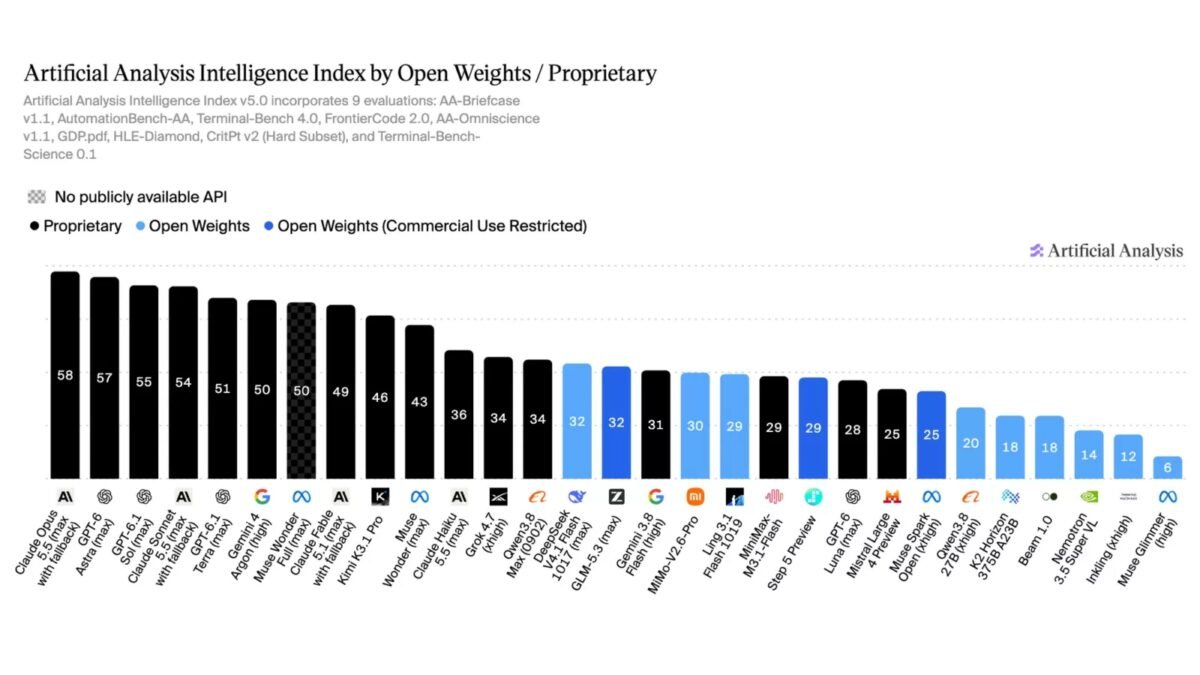
A fresh intelligence ranking has delivered a stark reality check for open-weight AI models, revealing a chasm between proprietary systems and their freely accessible counterparts. The gap between the top closed model and the best open one has quadrupled, jumping from 3 points to 12.
Artificial Analysis, the independent benchmarking firm, unveiled version 5 of its Intelligence Index this week. The overhaul marks its most significant update since January. Why? Roughly 60 percent of the evaluation now draws from private test data or held-out answers. That shift aims squarely at preventing models from memorizing publicly known questions during training.
The index weighs four categories equally: knowledge work, coding, science, and general knowledge. Each received tougher tests, including a private coding benchmark from Cognition called FrontierCode 2.0 and a new physics examination. Older tests like SciCode got dropped entirely.
The leaderboard saw little movement at the summit. Anthropic’s Claude Opus 5.5 held first place with 58 points. OpenAI’s GPT-6 Astra surged from 53 to 57, claiming second. Meanwhile, Meta’s Mapply Wonder Full plummeted from 56 to 50 points.
The damage cuts deeper among open-weight contenders. Moonshot AI’s Kimi K3.1 Pro remains the strongest open model, but slid from 55 to 46 points. DeepSeek V4.1 Flash collapsed from 45 to 32. Xiaomi’s MiMo-V2.6-Pro lost 16 points, landing at 30. The top American open model, Meta’s Mapply Spark Open, sank to 25 points.
As a result, the best model with released weights now trails the leader by 26 points. Even Anthropic’s low-cost Claude Haiku 5.5 beats every open model with published weights, scoring 36.
The new benchmarks demand far more computing power. Median output per task reached 59,000 tokens, up two-thirds from prior versions. A single run of Claude Opus 5.5 at maximum settings costs roughly $10 per question, compared to about $1.27 for GPT-6.1 Sol.
Yet the picture isn’t entirely one-sided. Kimi K3.1 Pro actually leads the entire field on Terminal-Bench 4.0, an agent test, outpacing every closed rival. The ranking also hinges on which tests a firm selects and how those scores get weighted. Since most data now stays secret, outsiders cannot independently verify results moving forward.